Booking Timeout and UNKNOWN Outcome Recovery
Recover ambiguous travel-booking timeouts with UNKNOWN state, authoritative lookup, reconciliation and safe retry gates.
A timeout on booking create does not prove that booking failed. Separating transport failure from business outcome is one of the most important safeguards against duplicate reservations.
Recovery state machine
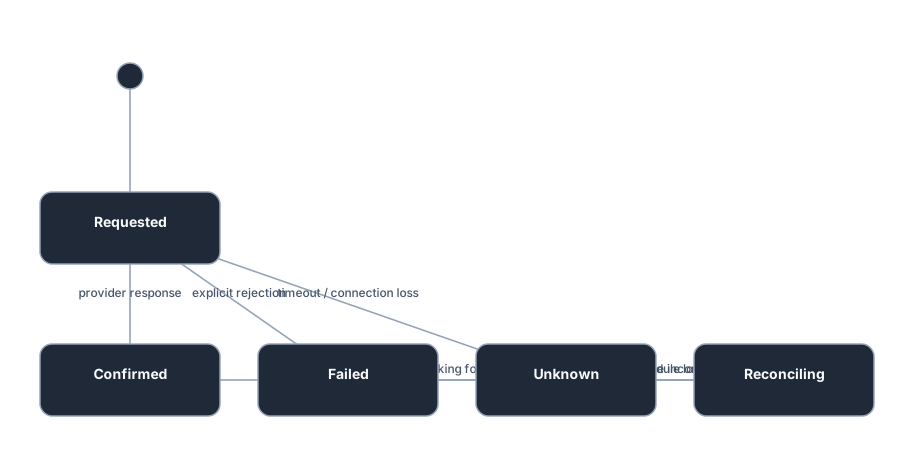 UNKNOWN booking recovery
Timeout classes
Separate connect timeout, read timeout, connection reset, client timeout and provider business timeout. Some indicate that the request may never have reached the provider; others mean the provider may have completed the booking while the response was lost.
Recovery identities
Persist identities useful for lookup: client reference, idempotency key, provider token/session, traveler + product fingerprint, payment reference and correlation ID.
Safe retry gate
Retry create only when the previous attempt is terminally FAILED and either the provider guarantees duplicate protection or authoritative evidence proves that no booking exists. Never blindly retry while state is UNKNOWN.
Reconciliation algorithm
if providerReference exists:
  lookup by providerReference
else if clientReference supported:
  lookup by clientReference
else:
  query narrow booking window / fingerprint
if found:
  CONFIRMED
else if provider guarantees lookup completeness:
  FAILED
else:
  remain UNKNOWN and escalate/backoff
"Not found" does not always mean "does not exist"; understand the provider's consistency guarantees.
User experience
Do not expose UNKNOWN as a raw technical status. Show a traveler-safe pending state, temporarily disable another purchase attempt, continue recovery and notify the user once the outcome is terminal.
Failure modes
Duplicate create retry, eventually-consistent lookup, false fingerprint matches, never-ending UNKNOWN state, manual creation of a second booking and using payment state as proof of booking outcome.
Observability
Track UNKNOWN creation rate, age percentiles, resolution source/outcome, duplicate-prevention hits, manual escalation and time-to-confirm/time-to-fail.
Production checklist
Use first-class UNKNOWN state, timeout taxonomy, persisted recovery identities, a provider lookup capability map, safe retry gates, backoff, manual escalation and traveler-safe pending UX.
Are you facing this in production?
We can review the symptom, data flow and integration behavior technically.
Related content
Booking Timeout / Outcome Unknown Troubleshooting
Diagnose ambiguous travel-booking timeouts without duplicate retries using evidence, authoritative lookup and reconciliation.
Explore →Booking Timeout & Duplicate Prevention Playbook
Handle unknown booking state after create timeouts using idempotency, lookup, payment evidence and reconciliation instead of blind retries.
Explore →Hotelbeds API Suite: Bedbank Distribution Profile
A technical profile of the HBX Group Hotelbeds API Suite covering hotel booking, content and cache APIs for B2B accommodation distribution.
Explore →OTA vs Metasearch vs Travel Marketplace: Key Differences
Compare OTA, metasearch and travel-marketplace models by transaction ownership, supplier relationships, monetization, handoff and technical architecture.
Explore →Package Holiday vs Hotel Metasearch: Architecture Differences
Compare package-holiday distribution with hotel metasearch by offer identity, pricing, supplier topology, booking ownership and cancellation.
Explore →Sabre Travel APIs: GDS and Travel Distribution Profile
A technical profile of Sabre Travel APIs covering air, lodging, car, booking and agency workflows across a GDS-oriented B2B platform.
Explore →